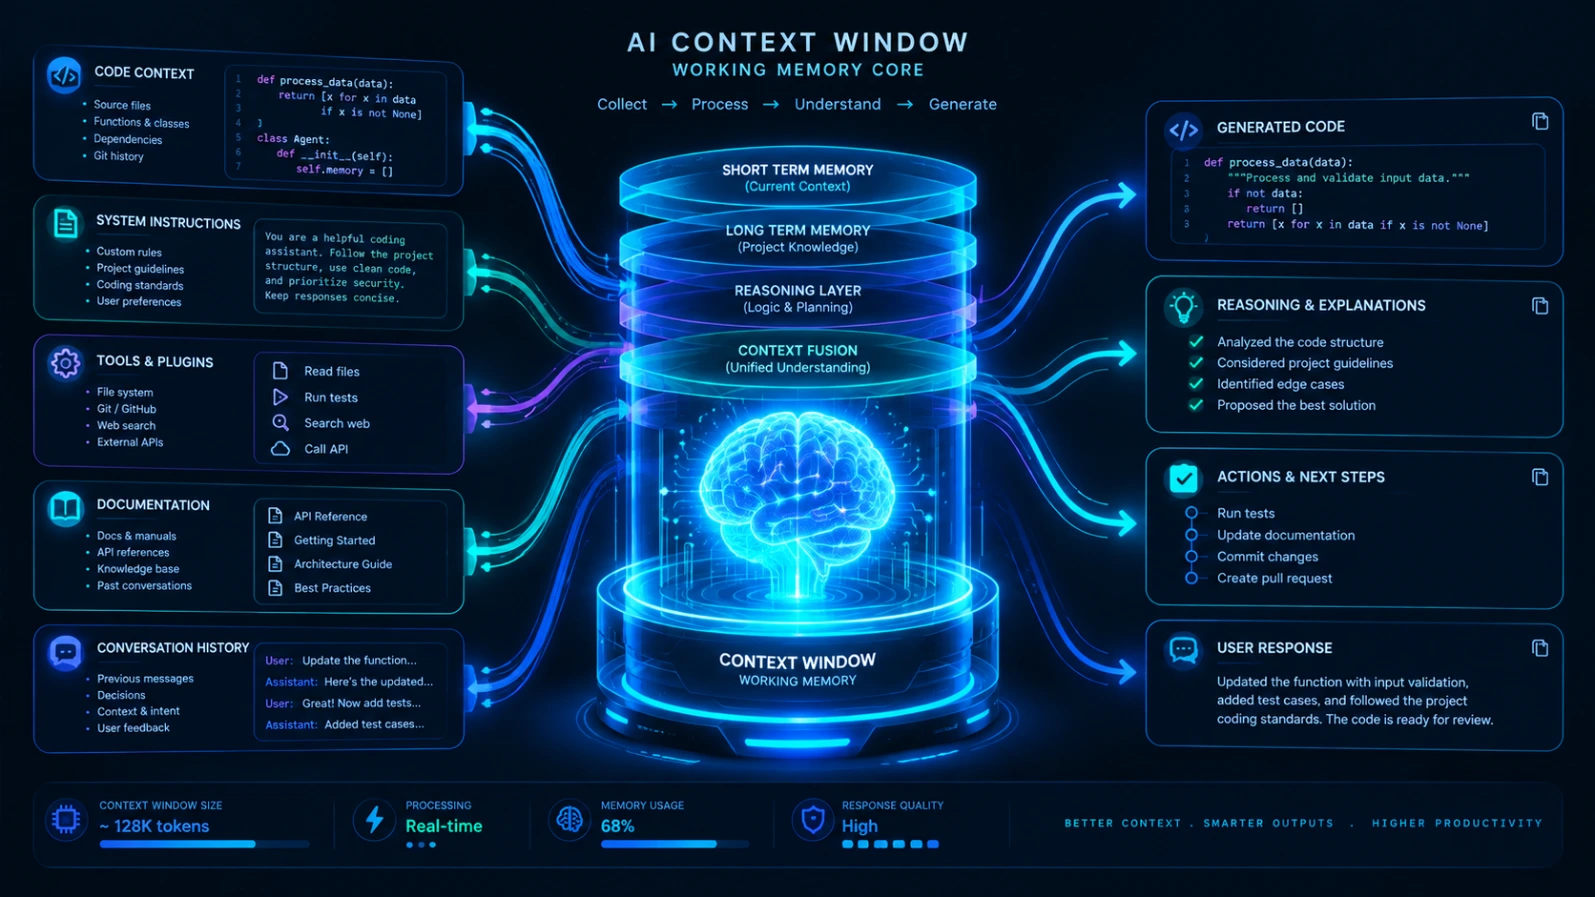
If Claude Code suddenly seems to forget what you told it ten minutes ago, starts re-reading files it already inspected, or gives weaker answers during a long coding session, the problem may be your context window.
Claude Code has a finite amount of working memory for each session. Your prompts, files, tool results, instructions, memory, MCP information, and Claude's responses all compete for that space.
Once you understand what fills the context window, what happens when it gets full, and how compaction works, many of Claude Code's "it forgot what I said" problems become much easier to understand.
This guide explains how the Claude Code context window works, what consumes it, how 200K and 1M-token contexts differ, what survives compaction, and how to monitor your own context usage.
Quick Answer: What Is the Claude Code Context Window?
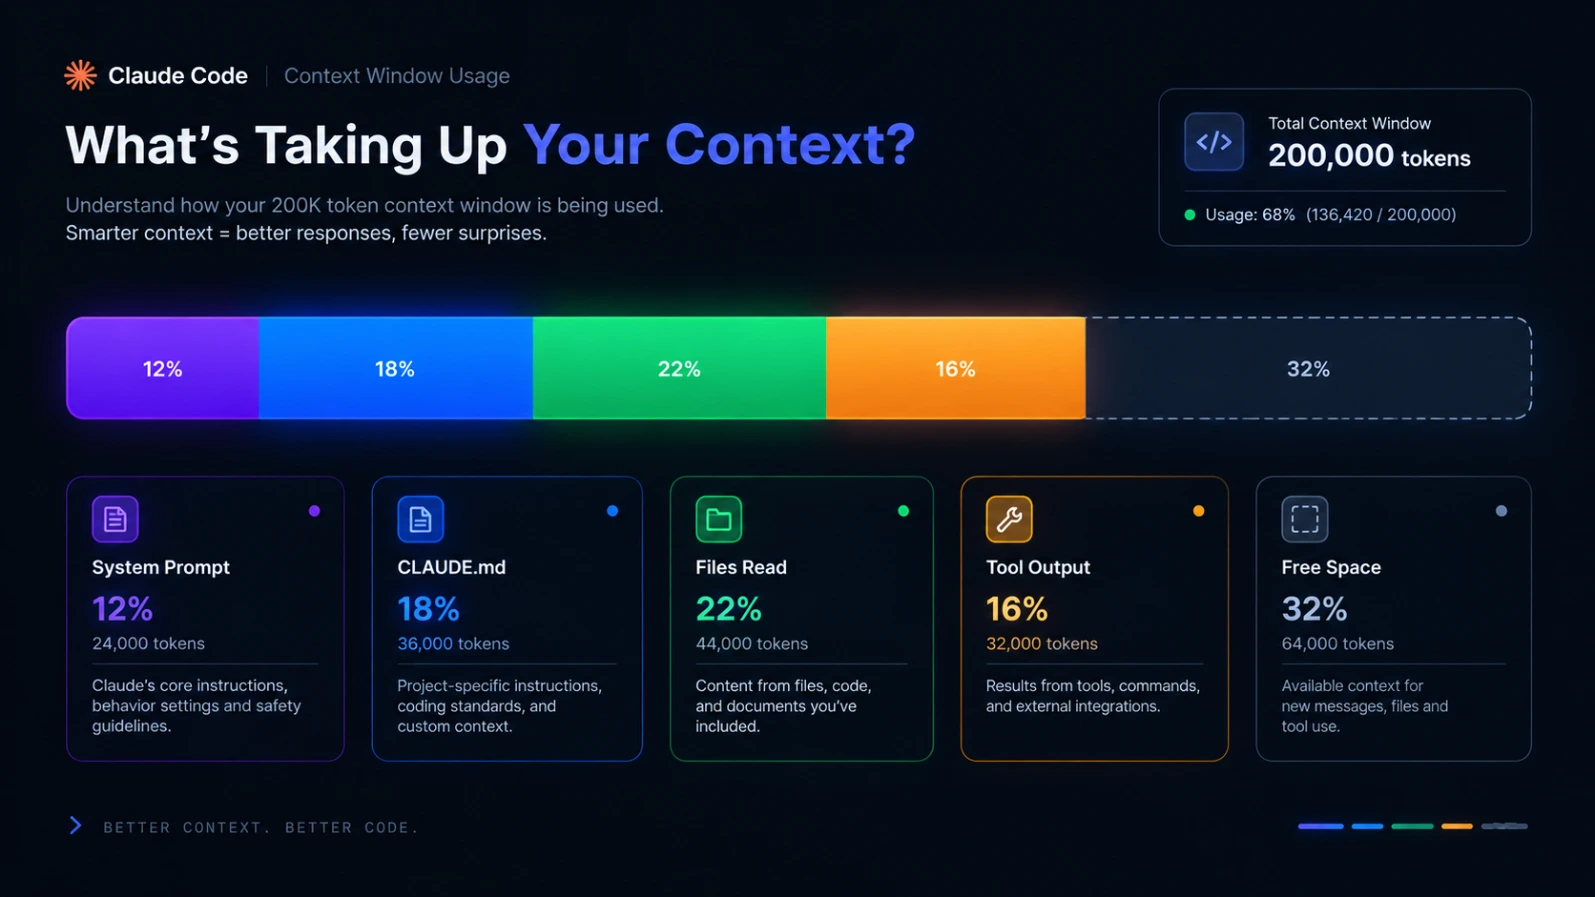
The Claude Code context window is the amount of information Claude can have available while working on your current task.
It includes much more than your conversation.
Depending on your setup, the context can contain:
- Your prompts and instructions
- Claude's previous responses
- Files Claude has read
- Tool results
- Command output
- Project instructions from CLAUDE.md
- Auto memory
- MCP tool information
- Skills and their descriptions
- Path-specific rules
- Hook output
- Other system-level information
Anthropic describes it as everything Claude knows about the current session at a given point.
A useful way to think about it is short-term working memory for your coding session.
It is not the same thing as permanent memory.
Information that needs to survive across sessions should generally be stored somewhere Claude can reload it, such as CLAUDE.md, a project plan, or another project document.
How Big Is the Claude Code Context Window?
For Claude Code, the available context size depends on the model.
A 200,000-token context window is the standard size for many models.
Claude Code also supports a 1-million-token context window on supported models, including:
- Sonnet 5
- Opus 4.6 and later
- Sonnet 4.6
- Fable models
Sonnet 5 runs with the 1M context window without requiring a separate [1m] variant. Supported Opus and Sonnet models can use the extended context configuration where available.
The important point is that context-window size is model-dependent. You should not assume every Claude model available in Claude Code has a 1M-token window.
200K vs. 1M Context
| Context | What it means |
|---|---|
| 200K tokens | Large enough for many normal coding sessions |
| 1M tokens | Much more room for large projects and long-running tasks |
| Larger context | More room before compaction, but not unlimited memory |
| Smaller context | Requires more deliberate session management |
A 1M context window does not mean Claude will automatically understand every detail equally well.
Long-context performance can still degrade when important information becomes buried inside a huge amount of surrounding material.
In other words:
More context gives Claude more room. It does not guarantee better use of every piece of information inside that room.
This is also reflected in community experience. Some Claude Code users report deliberately compacting or starting a new session around 100K–150K tokens even when using larger context windows. That's a workflow preference rather than an official Claude Code limit.
Context Window vs. Usable Context
There is an important distinction between the maximum context window and the amount of space actually available for your work.
Suppose your model supports 200,000 tokens.
That doesn't mean all 200,000 tokens are available for your next prompt.
Claude Code itself consumes part of the context.
Before you even start doing serious work, the session can already contain things such as:
- System instructions
- Project-level CLAUDE.md
- Auto memory
- MCP tool names
- Skill descriptions
- Environment information
- Other configured instructions
Claude Code's current context visualization shows categories such as system prompt, tools, MCP tools, memory, messages, free space, and the reserved auto-compaction area.
So think about the calculation like this:
Total context capacity − startup overhead − accumulated work = remaining context
That remaining space is what Claude has available for the next stages of your task.
What Fills the Claude Code Context Window?
Context consumption comes from two broad categories:
- Information loaded into the session automatically
- Information accumulated while Claude works
Understanding the difference is one of the easiest ways to manage context effectively.
What Loads Before You Type Anything?
Claude Code can load important project and environment information before you even send your first coding request.
This can include:
System prompt
Claude Code has system-level instructions that define how the agent behaves and uses its tools.
CLAUDE.md
Project instructions can be loaded automatically.
These instructions are particularly important because they can be re-injected after compaction.
Auto memory
Claude Code can maintain auto-memory information that is reloaded into future sessions.
You can manage memory through:
/memory
MCP tool information
MCP integrations can add tool information to the session.
The current Claude Code context documentation distinguishes the initial MCP tool information from full tool usage. Tool schemas can be deferred until they are actually needed, which helps prevent every possible MCP schema from consuming the full context at startup.
Skill descriptions
Available skills can also contribute information to the initial context.
The actual body of an invoked skill can be loaded when needed.
This means simply having many skills installed does not necessarily mean their complete instructions are sitting in the context at all times.
What Gets Added While Claude Works?
This is where context can grow quickly.
1. Files Claude Reads
File contents are often one of the biggest sources of context consumption.
For example, if you ask:
Read the entire repository and find the authentication bug.
Claude may need to inspect many files.
Every relevant file read can add information to the session.
That's why a more focused prompt can sometimes save substantial context.
Instead of:
Find what's wrong with login.
try:
Investigate the login failure in src/auth/login.ts. Start by checking the authentication flow and related error handling. Don't read unrelated directories unless necessary.
The second instruction gives Claude a narrower search path.
2. Tool and Command Output
Every tool call can produce information that becomes part of the working context.
Examples include:
- Test results
- Build logs
- Git output
- Search results
- Stack traces
- API responses
- Shell commands
- File listings
A huge error log can therefore consume a surprising amount of context.
This becomes particularly important during debugging because developers often repeatedly paste:
- Error messages
- Stack traces
- Test output
- File contents
- Previous attempts
A long debugging loop can fill context much faster than a simple coding task.
3. Your Prompts and Claude's Responses
The conversation itself also consumes context.
Long explanations, repeated requirements, copied code, and multiple iterations all add up.
This is one reason long sessions can eventually become less efficient even when you're working on the same project.
4. Hooks and Other Dynamic Context
Hooks can also add information to the context.
Claude Code documentation specifically notes that hook output can contribute context through additionalContext.
This is easy to overlook because the information may not look like part of your normal conversation.
If a hook repeatedly injects large amounts of information, it can become a hidden context consumer.
What Does NOT Stay in Your Main Context?
One of the most useful Claude Code features for context management is subagent isolation.
Subagents Have Their Own Context Window
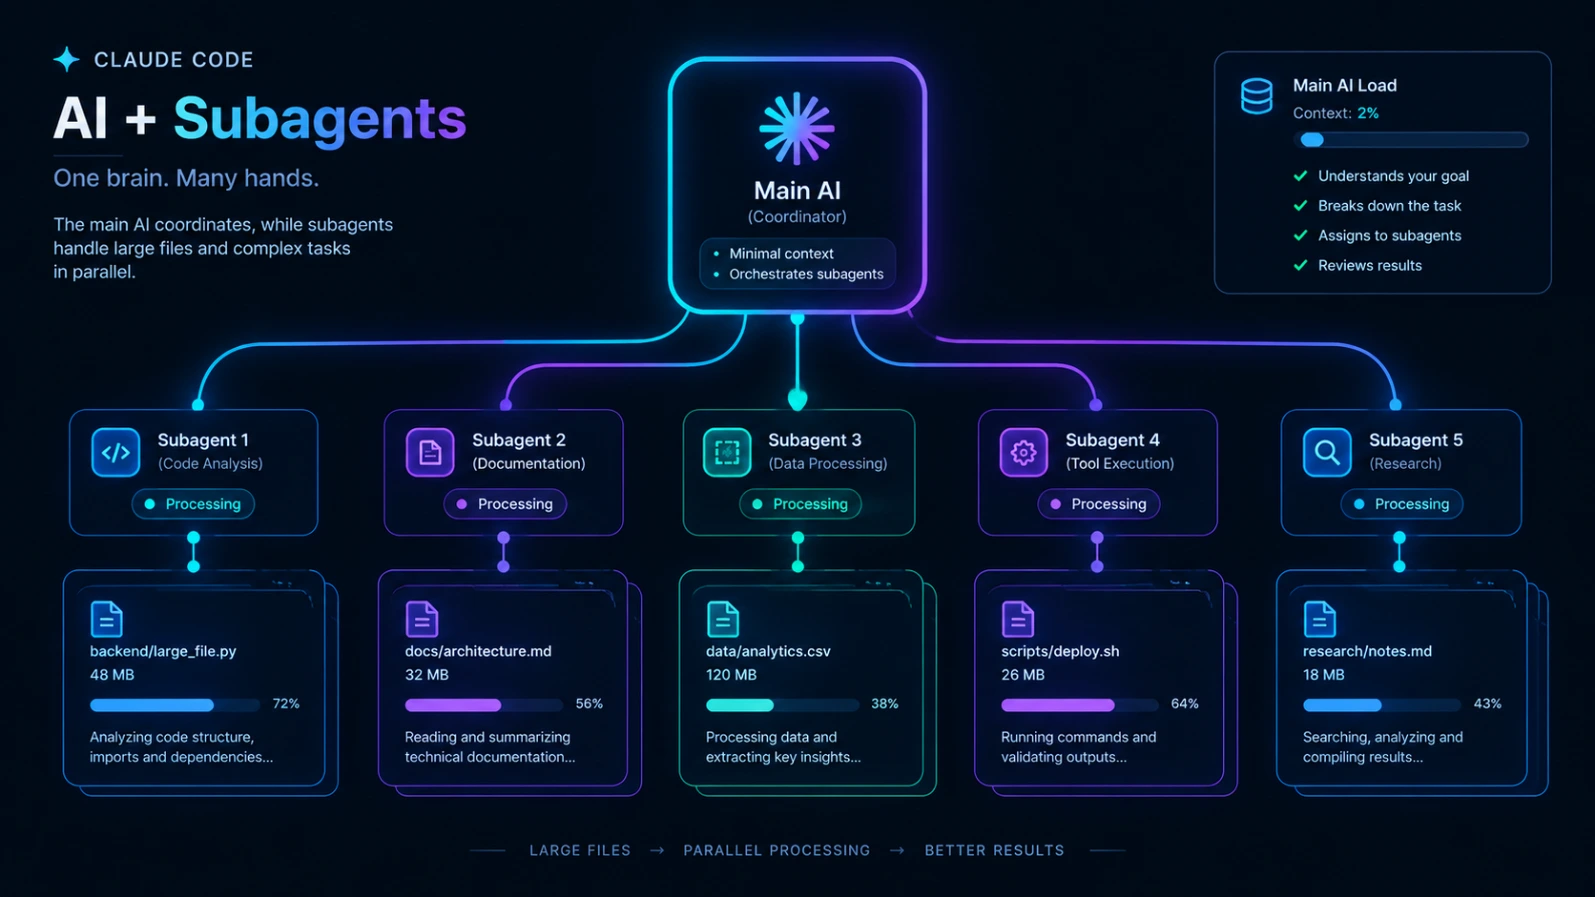
When Claude Code delegates work to a subagent, that subagent gets a separate context window.
For example, imagine you ask Claude to investigate:
Find every authentication endpoint and explain how they connect.
A subagent can inspect multiple files and perform the research inside its own context.
Your main session doesn't have to absorb every file read and tool result.
Instead, the main Claude session receives the result or summary.
Anthropic's current context documentation specifically highlights this as a way to keep large research tasks from consuming the main session's context.
This leads to a useful rule:
If you only need the result of a large investigation, consider delegating the investigation to a subagent.
Why Your Claude Code Session Can Feel Worse Before the Context Is Full
Reaching the maximum context size isn't the only problem.
Claude can become less effective during very long sessions before the context reaches its absolute limit.
As more information accumulates, important instructions and decisions can become surrounded by:
- Old tool results
- Previous experiments
- Outdated assumptions
- Large file contents
- Debugging attempts
- Repeated conversation
This can create what developers often describe as context rot.
You may notice symptoms such as:
- Claude repeating an earlier mistake
- Claude forgetting an architectural decision
- Claude re-checking files unnecessarily
- Responses becoming slower
- Claude focusing on old information
- Previously stated instructions receiving less attention
Community reports describe users intentionally ending or compacting long sessions before reaching the theoretical maximum for exactly this reason.
However, this should not be confused with a documented hard failure threshold. A developer's preferred "fresh start" point is a workflow choice, not an official Claude Code limit.
What Happens When the Context Window Gets Full?
Claude Code is designed to automatically compact the session as it approaches the context limit.
Instead of simply stopping at the maximum, Claude Code summarizes the conversation so the session can continue.
The basic process looks like this:
Long conversation
       ↓
Context fills
       ↓
Automatic compaction
       ↓
Conversation summarized
       ↓
Durable project information reloaded
       ↓
Session continues
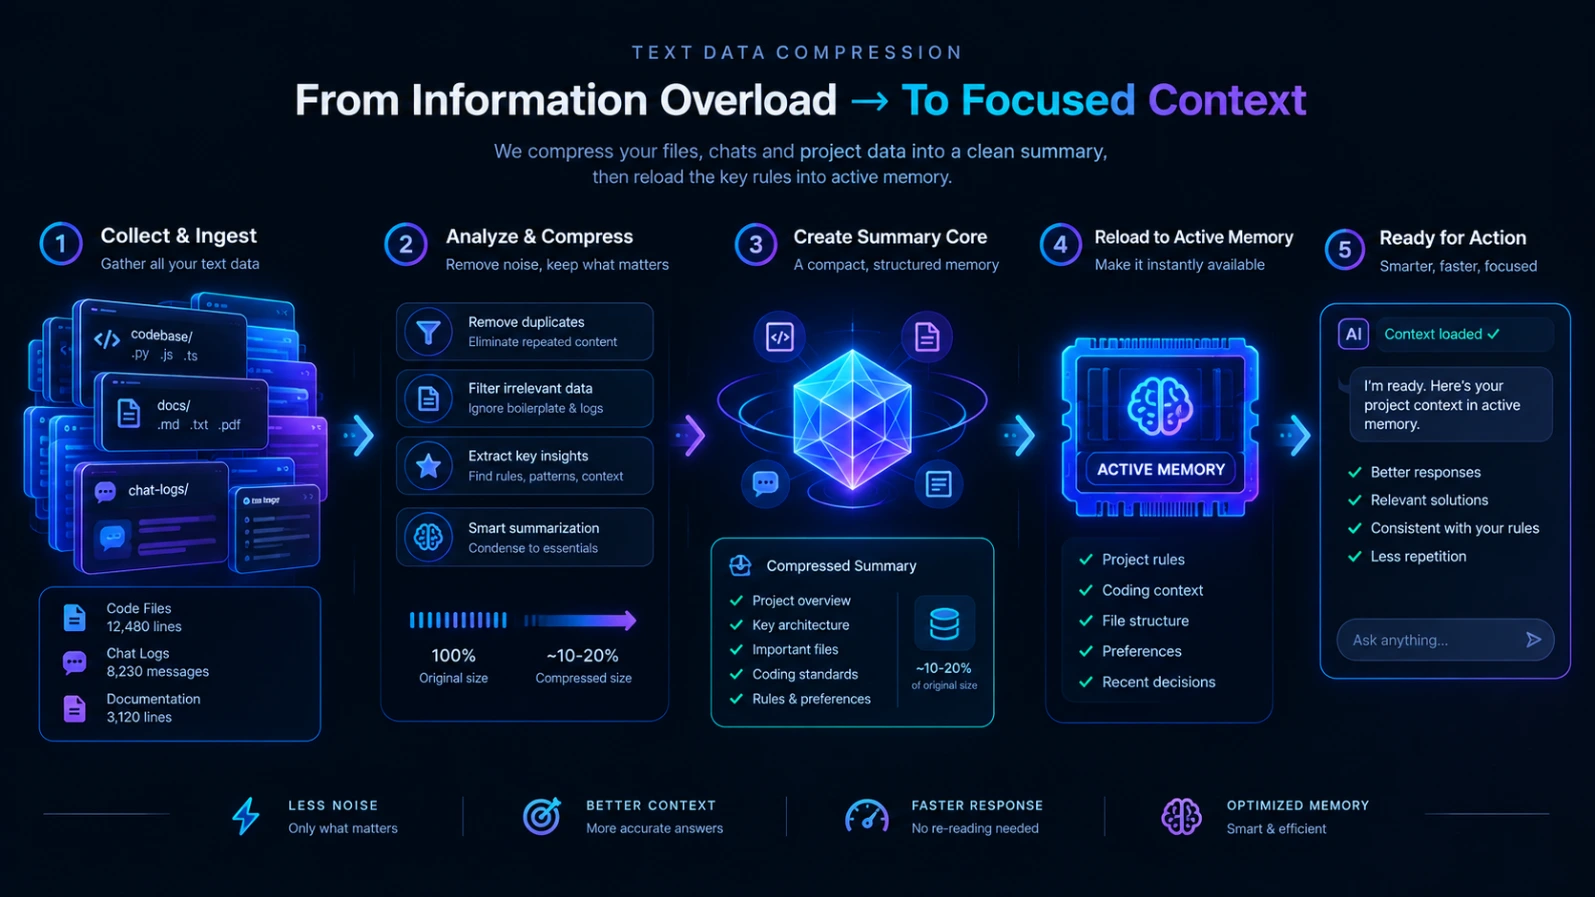
Anthropic's documentation says automatic compaction works similarly to running /compact manually.
But compaction is not a perfect backup of your entire conversation.
It is a summary, not a word-for-word copy.
What Survives Claude Code Compaction?
This is one of the most important parts of understanding context management.
After compaction, several types of information are restored automatically.
System prompt and output style
These continue to apply.
Project-root CLAUDE.md
Project instructions are re-injected from disk.
Unscoped rules
These can also be reloaded.
Auto memory
Auto memory is re-injected from disk.
Plan
If Claude created a plan in plan mode, the plan is stored and re-injected.
Path-scoped rules
Rules containing paths: are reloaded when Claude reads files matching those rules.
Nested CLAUDE.md files
Nested project instructions are loaded again when Claude reads files in the relevant directory.
Recently read or edited files
After compaction, Claude Code can re-read up to five of the files it read or edited, prioritizing the most recently modified ones.
This behavior is important because it means compaction doesn't simply wipe everything and leave Claude completely blind.
What Does NOT Survive Compaction Perfectly?
Compaction summarizes the conversation instead of preserving every detail word-for-word.
That means information such as:
- Full tool output
- Exact previous responses
- Intermediate reasoning
- Old debugging output
- Very specific instructions buried deep in the conversation
may no longer exist verbatim after compaction.
This is why important long-term instructions should not live only inside a conversation.
Put durable information into project files instead.
An Important Detail: Large Files After Compaction
There's another subtle behavior worth knowing.
If a file is larger than 5,000 tokens, Claude Code may bring it back as a path reference instead of restoring its entire contents after compaction.
The file can appear as a referenced file rather than a fully read file.
Its applicable rules can still reload.
This is one reason a large repository isn't necessarily restored exactly as it looked before compaction.
What Happens to Skills After Compaction?
Invoked skills can also be re-injected after compaction.
But there are limits.
Claude Code currently caps each skill's restored content at 5,000 tokens, with a total cap of 25,000 tokens across invoked skills.
Older invoked skills are dropped first when the total budget is exceeded.
This is another reason not to put enormous amounts of instructions inside every skill.
/compact vs. Automatic Compaction
Claude Code can compact automatically, but you can also trigger compaction yourself.
Run:
/compact
This summarizes the earlier conversation while allowing the session to continue.
You can also give it a focus.
For example:
/compact focus on the authentication bug, current implementation, failed attempts, and next steps
This is useful because you are telling Claude what information matters most in the summary.
Anthropic's documentation specifically recommends focused compaction when you want to preserve particular information before starting another task.
/clear vs. /compact
These commands are not interchangeable.
| Command | What it does | Best use |
|---|---|---|
| /compact | Summarizes existing context | Continue the same task |
| /clear | Starts fresh by removing conversation context | Switch to unrelated work |
| /context | Shows current context usage | Monitor context |
| /memory | Opens memory/instruction files | Manage persistent information |
| /rewind | Lets you go back and summarize from a selected point | Remove older parts while keeping newer work |
Claude Academy gives a similar rule: use /compact when you need to continue the current feature, and /clear when starting a genuinely new feature or task.
When Should You Use /clear?
Use /clear when the old conversation is no longer useful.
For example:
Finish authentication bug
        ↓
Task complete
        ↓
/clear
        ↓
Start database migration task
Carrying an old conversation into an unrelated task can make the new session noisier and consume context unnecessarily.
Claude Academy specifically recommends using /clear when starting a new feature so old conversation history doesn't introduce unnecessary context or bias.
How to Preserve Work Before /clear
This is where CLAUDE.md and project state files become extremely useful.
A practical workflow is:
1. Check /context
2. Ask Claude to summarize current work
3. Save important decisions to a project file
4. Update CLAUDE.md if the information is permanent
5. Run /clear
6. Start a fresh session
7. Tell Claude to read the relevant files
For example:
Before we start a new session, update the project state with:
- what we completed
- current architecture decisions
- files changed
- remaining bugs
- next steps
Then save that information in something like:
project_state.md
This approach is also reflected in community workflows. One Reddit discussion described developers using a running project-state file or updating CLAUDE.md before clearing a session so the next session can continue with the important information instead of relying on old conversation history.
Why CLAUDE.md Matters So Much
CLAUDE.md is not simply a documentation file.
For Claude Code, it can act as a persistent instruction layer.
For example:
# Project Rules

- Use TypeScript.
- Do not modify generated files.
- Run tests before committing.
- Use PostgreSQL for persistence.
- Keep API responses backward compatible.
Because project-level CLAUDE.md content is re-injected after compaction, important project rules have a much better chance of surviving than instructions that existed only in a previous conversation.
That gives you a useful principle:
Conversation is temporary context. Project files are durable context.
How to Check Your Claude Code Context Usage
Don't guess how full your context is.
Use:
/context
Claude Code provides a live breakdown of the context being used.
Depending on your setup, the display can show categories such as:
- System prompt
- System tools
- MCP tools
- Custom agents
- Memory files
- Messages
- Free space
- Reserved auto-compact buffer
It also provides suggestions for reducing context usage.
For example, you might see something conceptually similar to:
101k / 200k tokens
The exact numbers depend on your model and session.
The important thing is not just the percentage.
Look at which category is consuming the context.
If MCP tools are unusually large, your solution may be different from a session where massive file reads are responsible.
Use /memory to Manage Persistent Context
You can also run:
/memory
This opens the memory and CLAUDE.md files Claude Code uses.
That makes /memory useful when you want to inspect or update information that should survive beyond the current conversation.
A simple workflow is:
/context → identify the problem
/memory  → inspect persistent instructions
/compact → preserve the current task
/clear   → start fresh when appropriate
How to Reduce Claude Code Context Usage
You don't need to constantly fight the context window.
A few workflow changes can make a major difference.
1. Give Claude Specific Prompts
Specific prompts reduce unnecessary exploration.
Instead of:
Fix the login problem.
try:
Investigate the 403 response from src/auth/login.ts.
Check the OAuth callback and token validation first.
Don't inspect unrelated modules unless they are directly involved.
Claude Academy specifically recommends being specific because vague requests can cause Claude to explore more of the codebase, consuming additional context.
2. Don't Dump the Entire Repository
Giving Claude access to an entire codebase doesn't mean it needs to read every file.
Large repository-wide reads can consume context rapidly.
A better approach is:
Find the relevant files
        ↓
Read the smallest useful sections
        ↓
Make the change
        ↓
Run targeted tests
Community reports also describe developers getting better results by splitting large repository tasks into smaller file-focused tasks.
3. Use Subagents for Large Research Tasks
If you need Claude to investigate a large codebase but only need the final answer, a subagent can keep that research outside your main context.
For example:
Use a subagent to find all authentication endpoints
and return a concise summary of their relationships.
The subagent handles the exploration in its own context.
Your main session receives the useful result instead of every intermediate file read.
4. Keep MCP Integrations Relevant
MCP tools can become part of your context environment.
If you have many MCP servers configured but only use one or two for the current project, unnecessary integrations can add overhead.
Claude Academy recommends managing MCP servers and disabling integrations that aren't relevant to the current project.
5. Use /compact Before a Major New Phase
You don't always need to wait for automatic compaction.
For example:
Feature implementation complete
        ↓
/compact focus on current architecture and remaining TODOs
        ↓
Begin testing/refactoring
This can produce a cleaner context for the next stage.
6. Use /clear Between Unrelated Tasks
If you're moving from:
Authentication
to:
Database migration
there may be little reason to carry the entire authentication conversation forward.
Start clean and load only the information required for the new task.
What Is Autocompact Thrashing?
There is an important edge case that many Claude Code users don't know about.
Sometimes Claude Code successfully compacts the context, but the context immediately fills again because a very large file or tool result gets reintroduced.
This can create a loop:
Context full
   ↓
Compact
   ↓
Large file/tool output loaded
   ↓
Context full again
   ↓
Compact
   ↓
Large output loaded again
Claude Code calls this autocompact thrashing.
The current troubleshooting documentation says Claude Code can stop retrying after repeated refills to prevent wasting API calls.
How to Fix Autocompact Thrashing
Try these approaches:
- Ask Claude to read the large file in smaller chunks.
- Use a focused /compact.
- Move large-file investigation to a subagent.
- Use /clear if the previous conversation is no longer important.
For example:
Read only lines 1-300 of the file first.
Don't load the entire file into context.
This can be much more efficient than asking Claude to process a massive file all at once.
Context Window Is Not the Same as Your Usage Limit
This distinction is extremely important.
A context window limit applies to the amount of information Claude can hold in one working session.
A usage limit applies to how much Claude you can use under your account or plan.
They are different things.
You can therefore have:
Large remaining context
+
Low account usage remaining
or:
Plenty of account usage
+
A nearly full context window
Starting a new session or running /clear can reset the conversation's context state, but it does not reset your account's usage allowance.
This distinction is particularly important when debugging claims that Claude is "using too many tokens."
Does a Bigger Context Window Mean Better Performance?
Not necessarily.
A larger context window mainly gives Claude more room to work.
It doesn't guarantee that every piece of information inside that window receives equal attention.
For example, imagine a 1M-token session containing:
- 300K tokens of source code
- 100K tokens of logs
- 200K tokens of tool results
- 100K tokens of conversation
- 100K tokens of documentation
- 200K tokens of other context
Claude technically has access to a huge amount of information.
But your important instruction might still be buried inside hundreds of thousands of unrelated tokens.
That's why good context management remains important even with 1M-token models.
The goal isn't:
Put everything into context.
The goal is:
Put the right information into context at the right time.
A Practical Claude Code Context Management Workflow
For long coding projects, this workflow is a good starting point:
Step 1: Start with persistent instructions
Keep stable project rules in:
CLAUDE.md
Step 2: Give a focused task
Tell Claude:
- What needs to change
- Which files matter
- What constraints exist
- What success looks like
Step 3: Monitor the context
Run:
/context
during long sessions.
Step 4: Compact intentionally
When you're finishing one phase and continuing with the same feature:
/compact focus on the current implementation, decisions, files changed, and remaining work
Step 5: Save durable state
Keep important architecture decisions, plans, and next steps in project files.
Step 6: Clear when changing tasks
Use:
/clear
when the previous conversation is no longer useful.
Step 7: Delegate large investigations
Use subagents when you need large amounts of exploration but only need the final findings.
This creates a much cleaner relationship between your project files, conversation context, and agent work.
Why Claude Code Sometimes "Forgets" What You Said
If Claude suddenly appears to forget something, don't immediately assume the model is broken.
Check these possibilities:
1. The context became very large
The instruction may be buried among a large amount of conversation and tool output.
2. Compaction occurred
The original conversation may have been summarized.
3. The information was never stored persistently
If the instruction mattered across sessions, it may belong in CLAUDE.md or another project file.
4. A large file or tool result dominated the context
Claude may have spent significant context processing information unrelated to your latest request.
5. You changed tasks without clearing
Old context can interfere with the new task.
6. A subagent handled part of the work
The main Claude session may only have received the subagent's summary rather than every intermediate detail.
These are normal consequences of how context management works.
The Best Mental Model for Claude Code Context
Think of Claude Code as having three layers:
┌──────────────────────────────────────┐
│        Persistent Project State      │
│ CLAUDE.md / project docs / memory    │
└──────────────────────────────────────┘
                  ↓
┌──────────────────────────────────────┐
│          Current Context             │
│ prompts / files / tools / outputs    │
└──────────────────────────────────────┘
                  ↓
┌──────────────────────────────────────┐
│       Model's Current Reasoning      │
│       what Claude is working on      │
└──────────────────────────────────────┘
The persistent layer is where important information should live long term.
The context layer is the working area.
The reasoning layer is what Claude is actively using to solve the current problem.
When the working context becomes too large, Claude Code can compact it.
The persistent information can then be loaded again.
That is why good project documentation is so important for agentic coding.
Frequently Asked Questions
What is the default Claude Code context window size?
Claude Code commonly uses a 200,000-token context window, while supported models can provide a 1-million-token context window. Current Claude Code documentation lists Sonnet 5, Opus 4.6 and later, Sonnet 4.6, and Fable models among the models supporting 1M context.
Does the context window reset between sessions?
Yes. A new session starts with a new conversation context.
However, persistent information such as project CLAUDE.md and auto memory can be loaded again because they exist outside the conversation itself.
Does /clear delete my project files?
No.
/clear clears the current conversation context. It does not delete your source code or project files.
Information stored in project files such as CLAUDE.md remains available to Claude when it is loaded again.
Does /compact delete the conversation?
No.
/compact summarizes earlier conversation context so the session can continue with less context usage.
However, the original conversation isn't guaranteed to remain available word-for-word after compaction.
What uses the most context in Claude Code?
There isn't one universal answer because it depends on the project.
Large file reads, tool output, messages, MCP-related information, memory, skills, and system instructions can all contribute.
Use:
/context
to see what's actually consuming your session.
How do I check my current context usage?
Run:
/context
Claude Code provides a categorized view of current context usage and optimization suggestions.
What is the difference between /compact and /clear?
Use /compact when you want to continue the current task with a summarized history.
Use /clear when you want to start fresh without the old conversation.
Claude Academy recommends /compact for continuing a feature and /clear when beginning a new feature or unrelated task.
Can subagents save context?
Yes.
Subagents use separate context windows, so large investigations can happen without filling the main agent's context with every intermediate file read and tool call.
Does a 1M context mean Claude can remember everything?
No.
A larger context provides more capacity, but it doesn't guarantee perfect attention to every piece of information inside that context.
You still benefit from focused prompts, persistent project documentation, targeted file reads, compaction, and clean session boundaries.
What should I do if Claude Code keeps auto-compacting?
First check:
/context
If the context repeatedly fills immediately after compaction, look for oversized files, large tool output, or hooks that inject a lot of information.
Claude Code's troubleshooting guidance recommends reading large files in smaller chunks, using focused /compact, delegating work to a subagent, or using /clear when the previous context is no longer needed.
Final Takeaway
The Claude Code context window is more than a token counter.
It is the working space where Claude combines your instructions, project files, tool results, memory, MCP information, and conversation history to solve a task.
The most important things to remember are:
- 200K tokens is still the common Claude Code context size, while supported models can use 1M.
- Your entire context isn't available for coding because system instructions and other session information consume space.
- Large file reads and tool output can fill context surprisingly quickly.
- CLAUDE.md and persistent project files are more reliable than old conversation messages for important instructions.
- Subagents use separate context windows and can keep large research tasks out of your main session.
- /context shows what's actually consuming your context.
- /compact summarizes a long session so you can continue working.
- /clear is better when switching to an unrelated task.
- Compaction preserves important durable information, but it does not preserve every old message word-for-word.
- A larger context window gives you more room, not a guarantee that Claude will use every detail equally well.
Once you start treating context as a resource instead of an invisible background feature, Claude Code becomes much easier to manage.
The goal isn't to keep the context window as full as possible.
The goal is to keep it relevant.